Markdown Token Counter
Count tokens in Markdown prompts for LLM workflows. Understand formatting, tokenizer differences, and prompt budget limits before sending text to a model.
Result
No estimate yetLocal analysis: auto content profile via detectProfile; fallback heuristic with range. How was this calculated? Exact = local tokenizer count, Estimated = heuristic range.
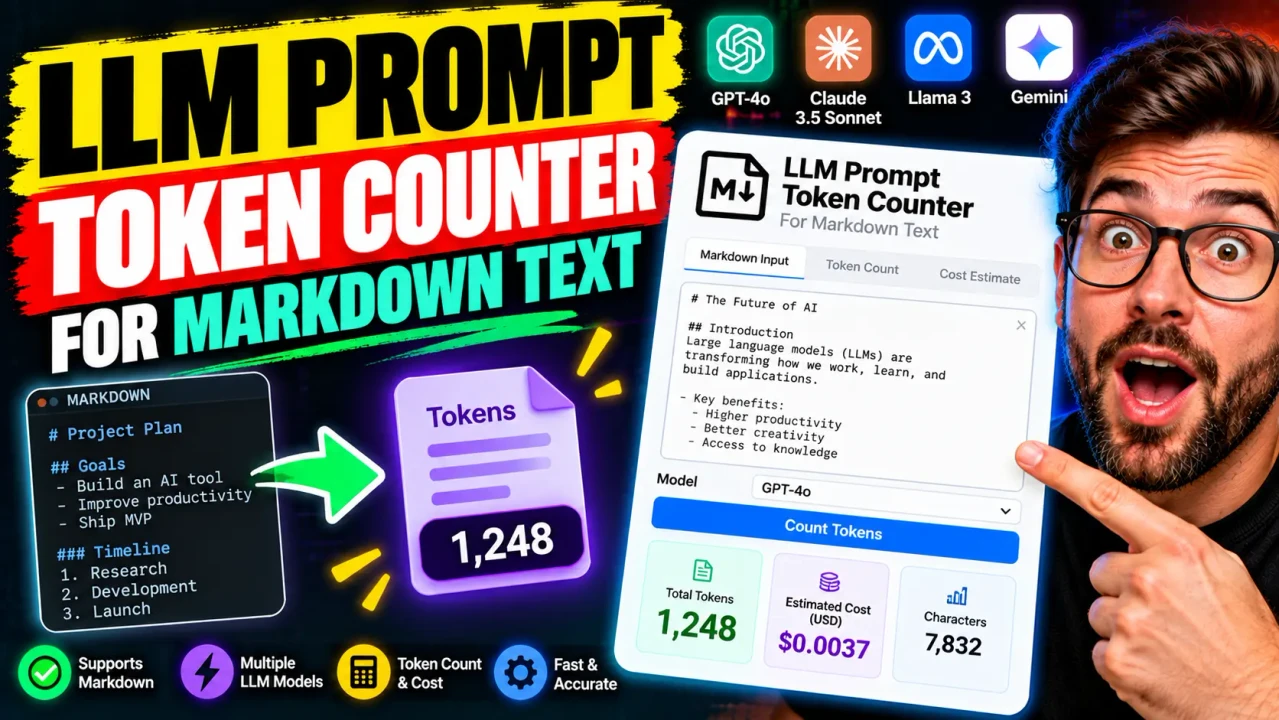
Llm Prompt Token Counter For Markdown Text
Quick answer: Llm Prompt Token Counter For Markdown Text is a developer utility designed to help users understand the token length of Markdown-formatted text before submitting it to a large language model (LLM). It is intended for prompt writers, AI application developers, researchers, and technical teams who need to assess prompt size against model context-window or token-budget constraints.
The Llm Prompt Token Counter For Markdown Text focuses on an important distinction in AI development: tokens are not the same as words, characters, or lines of Markdown. A prompt containing headings, code blocks, tables, links, and lists may have a token count that differs significantly from its word count. Understanding that difference helps when preparing system instructions, reusable prompts, documentation, and retrieval-augmented generation (RAG) content.
The tool's supplied name identifies Markdown text as its input subject and LLM prompt tokens as its measurement target. Its exact tokenizer, supported model families, output fields, processing architecture, and export options have not been specified. Consequently, token estimates should not be treated as verified model-specific counts unless the implementation explicitly identifies the tokenizer and model configuration used.
TL;DR / Key Takeaways
- Primary Function: Assess the token length of Markdown prompt text.
- Input: Markdown-formatted text, including prose and code.
- Purpose: Help manage prompt budgets and model context limits.
- Important Limitation: Exact counts depend on the tokenizer and model configuration.
How to Use Llm Prompt Token Counter For Markdown Text?
- Prepare your Markdown: Gather the actual prompt you intend to send to an LLM. Include headings, lists, code fences, tables, links, and instruction text that will be part of the request.
- Enter the text: Paste the Markdown into the tool's input area, following the interface's available input requirements.
- Run the count: Use the available counting action, if provided, to analyze the submitted text.
- Review the result: Compare the reported count with your intended model's token budget. Confirm the tokenizer used before relying on the result for a strict context-window limit.
These steps describe the expected workflow for a Markdown token counter. Exact control names and available output fields depend on the deployed implementation.
Input and Output Example
Consider this representative Markdown prompt:
# Support Assistant

Answer the user's question using the supplied documentation.

## Rules
- Be concise.
- Do not invent facts.
- Return valid JSON when requested.

## Example
```json
{"status": "ok", "count": 3}